
Introducing Parlon
Infrastructure observability.
Reimagined.
More visibility. Less complexity. Lower cost. Device telemetry, flow records, and synthetic tests land in one normalized platform. Your team spends less time connecting tools and more time fixing what matters.

Analyst recognition
EMA names Parlon a Vendor to Watch.
“Parlon addresses these challenges at the data layer, normalizing device telemetry, flow records, and synthetic traffic at ingestion.” Shamus McGillicuddy, Enterprise Management Associates (EMA)
The problem
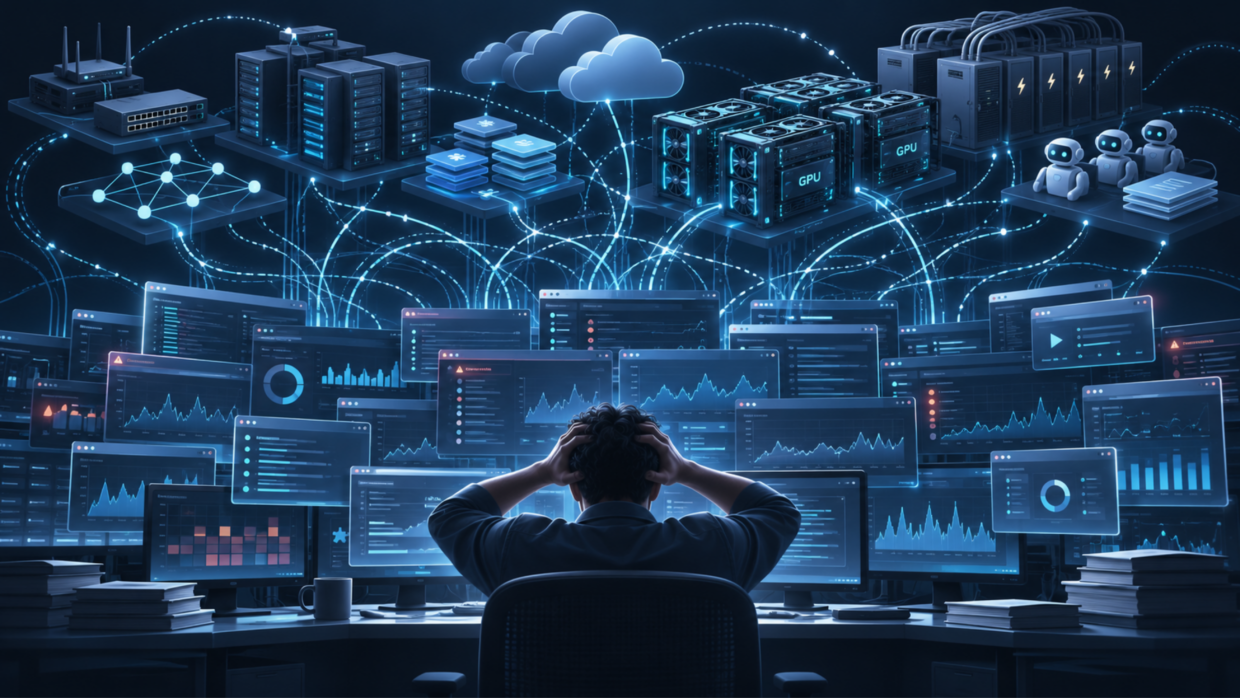
Your monitoring tools work. The stack is the problem.
Most teams rely on 4 to 10 tools to monitor and troubleshoot their networks. Each one works. Connecting them falls to people.
EMA Network Management Megatrends 2026 · EMA, The Reality of Observability Unification in Modern IT Operations, August 2026.
The Parlon difference
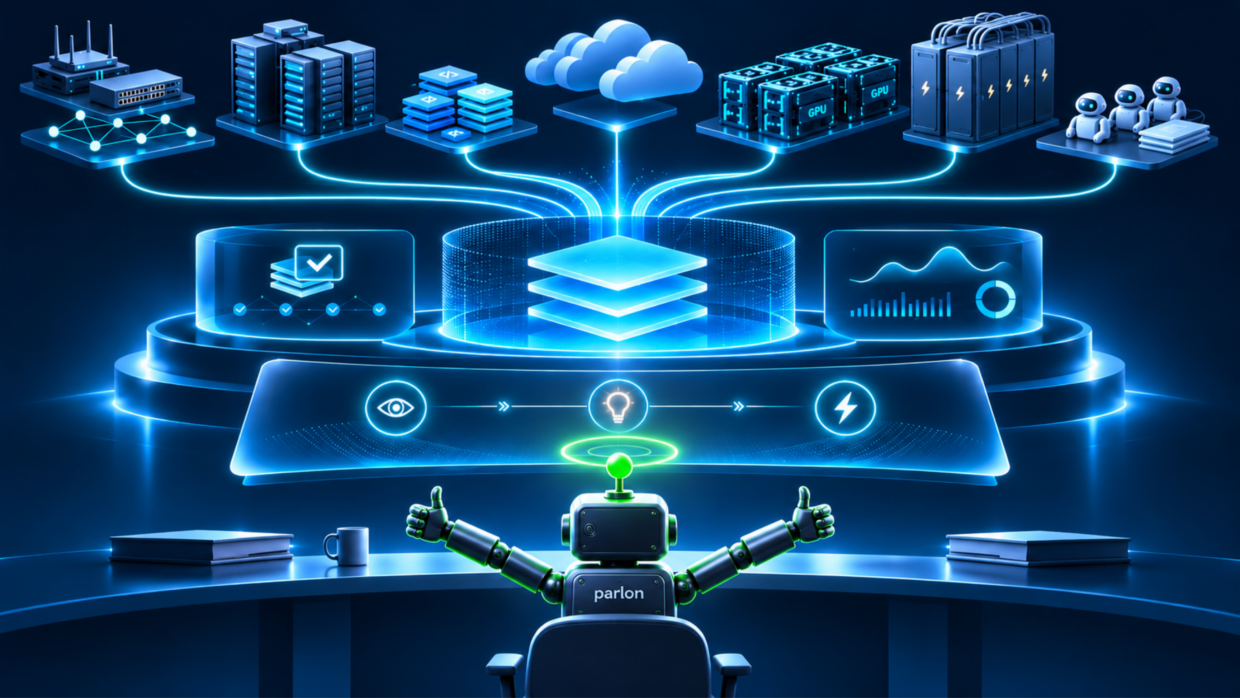
One foundation. Less work. Better answers.
Every source of infrastructure data feeds one foundation. Data is normalized as it arrives, so your team stops building integrations and reconciling tools.
- ConnectDevice data from more than 200 vendors and your synthetic tests land in one model.
- SimplifyFewer tools to integrate, tune, and administer.
- UnderstandService impact and infrastructure evidence appear side by side.
How it works
From raw telemetry to the exact hop.
Every device reports in its own format. Parlon collects it and puts it on one timeline. Then it tests the path and shows you where it breaks.
llm-inference-chat · detected from probe-bos-02leaf-03 eth1/7 → gpu-node-07 · +38 msChoose your route
Start where your problem is.
Three entry points, one platform underneath. Most teams start with active monitoring alongside the tools they already run.
What you already know
Telemetry tells you what happened. It does not tell you whether the path works right now.
Passive collection reports a condition after it exists. Active validation tests the path on purpose, on a schedule you set, before a user or a workload finds the fault for you.
EMA Network Management Megatrends 2026, n=352.
What Parlon does
- 01Native synthetics, not a module. Latency, availability, and path analysis in the same system as the telemetry.
- 02Active tests within hours. Including inside fully air-gapped environments.
- 03LLM-aware workflow checks. Validate the AI-dependent path, not only the network beneath it.
- 04One data model behind both. A synthetic result and a device metric correlate without a swivel chair.
The first question worth answeringHow long after a change do you know the path still works?
What you already know
Your network outgrew the tools watching it.
Hybrid cloud, SD-WAN, streaming telemetry, and flow records arrived faster than legacy NPM platforms adapted. Each tool still sees its own slice. During an incident, your team pieces the story together by hand.
EMA Network Management Megatrends 2026. Alert noise reduction: Parlon-reported.
What Parlon does
- 01Normalized at ingestion. SNMP, APIs, gNMI, streaming telemetry, and flow records land in one data model, with vendor detail preserved.
- 02The coverage you rely on. More than 200 vendors. Nobody re-cables a network or recertifies a device to run Parlon.
- 03Signal over noise. Alert Auto-Tune™ learns baselines and recommends thresholds, and a human approves them. Teams see about 70% less alert noise.
- 04Replace on your schedule. Run alongside your current platform, prove it in 30 to 60 days, then retire what you no longer need.
The first question worth answeringHow many tools does your team open before it knows where a problem is?
What you already know
AI workloads run on layers your observability does not reach.
A thermal-throttled GPU, a rack approaching breaker capacity, an agent reading production telemetry without attribution, a congested east-west path. None of these appear in an application trace, and none of them wait for a dashboard to be reconciled.
EMA Network Management Megatrends 2026, n=352.
What Parlon does
- 01Device-level GPU health. Available. Utilization, thermal throttle, and ECC/XID errors on a single device, not a cluster average.
- 02Power as a first-class signal. Available. Breaker-level load, A/B feed redundancy, and capacity runway before a rack trips.
- 03Agent activity, attributed. Read auditing live. Write governance is next. Every AI agent read is tied to a known identity and audit-logged.
- 04Fabric path, hop by hop. Coming soon: east-west traffic and fabric health across the cluster, on the same data model as everything above.
The first question worth answeringCan you see GPU health, power headroom, agent activity, and fabric path in one place today?
Evidence, with the record attached
One deployment, and what it established.
Enterprise healthcare, air-gapped and HIPAA-compliant
A multi-vendor stack across more than 1,000 clinic locations, datacenters, and remote branches, consolidated into one deployment: one data model, one console, one contract. Synthetics were active within hours inside a fully air-gapped environment with strict data-residency requirements.
We found Parlon's capabilities beyond parity with the legacy vendors, and the simplicity of deployment and the cost were a significant value in themselves. Network Infrastructure Lead, enterprise healthcare provider
The evidence record
What this result establishes
- Where observed: one production enterprise healthcare deployment.
- How measured: against the documented cost and staffing of the replaced multi-tool footprint.
- Configuration: on-premises, fully air-gapped, HIPAA-compliant, device monitoring and synthetic path testing.
The Parlon foundation
Four design choices behind the platform.
Parlon's differences sit in how the platform is built. Each one changes how your data is collected, connected, and acted on.
Normalization at ingest
Every source mapped to a unified schema the moment it arrives, with vendor detail preserved. Correlation is immediate rather than reconstructed.
Synthetics and telemetry, unified
Active testing and continuous collection in one native system, including LLM-aware workflow checks.
Alert Auto-Tune™
Threshold recommendations with the evidence behind them, approved by a human. When Parlon alerts, it is worth acting on.
Deploy anywhere
One codebase runs as SaaS, hybrid, on-premises, or air-gapped. Air-gapped runs in production today.
How to prove it
Prove the case before you make the decision.
A bounded proof, run alongside what you already have, on one question that matters. No estate-wide commitment, and no assumption about the result.
Every outcome counts
A credible proof can fail to justify a change.
A null result, an incomplete integration, retained incumbent capability, or a weak full-cost case are all valid conclusions. We would rather you reach one of them in 60 days than discover it in year two.
The full-cost review that sits alongside it covers current contracts and operating burden, proof and transition cost, coexistence scope, decommissioning feasibility, and residual risk.
Start the conversation